What is subquery in PostgreSQL?
In PostgreSQL, a subquery is a query that is nested inside another query. The subquery is executed first, and its results are used as input to the outer query. Subqueries can be used in various contexts, such as in the SELECT, WHERE, and HAVING clauses of a query.
For example, consider the following query that uses a subquery to find the total number of orders for each customer:
SELECT customer_id, COUNT(*) as num_orders
FROM orders
WHERE customer_id IN (
  SELECT id
  FROM customers
  WHERE country = 'USA'
)
GROUP BY customer_id;
In this query, the subquery `(SELECT id FROM customers WHERE country = ‘USA’)` is executed first to retrieve the IDs of all customers in the USA. The outer query then uses these IDs to count the number of orders for each customer.
A common alternative to using subqueries is to use Common Table Expressions (CTEs). A CTE is a named subquery that can be referenced multiple times within a single query. The primary benefit of using a CTE is that it can make a query easier to read and understand by breaking it down into smaller, more manageable parts.
For example, the previous query could be rewritten using a CTE like this:
WITH usa_customers AS (
  SELECT id
  FROM customers
  WHERE country = 'USA'
)
SELECT customer_id, COUNT(*) as num_orders
FROM orders
WHERE customer_id IN (
  SELECT id FROM usa_customers
)
GROUP BY customer_id;
In this query, the subquery `(SELECT id FROM customers WHERE country = ‘USA’)` has been replaced with a CTE called `usa_customers`. The CTE is defined using a `WITH` statement, and it can be referenced multiple times within the same query. The outer query then uses the CTE to count the number of orders for each customer in the USA.
Both subqueries and CTEs are powerful tools in PostgreSQL that can be used to create complex queries that retrieve and manipulate data in a variety of ways.
What is CTE in PostgreSQL?
A CTE is a named temporary result set that you can reference within a SELECT, INSERT, UPDATE, or DELETE statement. It allows you to break down complex queries into smaller, more manageable parts, making the query more readable and easier to understand.
Here is an example of a CTE that computes the average price of all products:
WITH product_avg_price AS (
  SELECT AVG(price) AS avg_price FROM products
)
SELECT * FROM product_avg_price;
In this example, the CTE is named “product_avg_price” and contains a single SELECT statement that computes the average price of all products. The main SELECT statement then references the CTE and returns the result.
Common Table Expressions (CTEs) have several advantages over subqueries
1. Readability: CTEs can make a query easier to read and understand by breaking it down into smaller, more manageable parts. This can be especially useful for complex queries that involve multiple subqueries.
2. Reusability: A CTE can be referenced multiple times within a single query, which can reduce the amount of redundant code and improve query performance.
3. Recursivity: CTEs can be used to create recursive queries, which allow you to traverse hierarchical or graph-like structures, such as a tree or a social network.
4. Performance: In some cases, using a CTE can be more efficient than using a subquery. This is because a CTE is executed only once, and its results are cached in memory, whereas a subquery is executed every time it is referenced in the outer query.
5. Debugging: CTEs can be a useful tool for debugging complex queries. By breaking a query down into smaller parts using CTEs, you can more easily identify and isolate errors or performance issues.
REF

Bài viết khác
Redis & Caching là gì?
Redis & Caching là gì? Hướng dẫn sử dụng Redis trong Go 1. Caching là gì? Vì sao cần cache khi đã có database? Caching (bộ nhớ đệm) là kỹ thuật lưu tạm dữ liệu thường được truy cập để có thể lấy lại nhanh chóng khi cần, thay vì phải thực hiện lại toàn […]
Database Migration là gì?
1. Database Migration là gì? Database Migration là quá trình quản lý và áp dụng những thay đổi đối với cấu trúc hoặc dữ liệu trong cơ sở dữ liệu theo từng phiên bản của ứng dụng. Trong quá trình phát triển phần mềm, yêu cầu nghiệp vụ thường xuyên thay đổi. Một bảng có […]
Bun ORM là gì?
Bun ORM là gì? Hướng dẫn sử dụng Bun ORM với Go và PostgreSQL 1. Bun ORM là gì? Bun là một thư viện ORM dành cho ngôn ngữ Go, được thiết kế theo hướng SQL-first. Thay vì cố gắng che giấu hoàn toàn SQL phía sau các phương thức trừu tượng, Bun cho phép […]
Redis & Caching – Hướng dẫn toàn diện về Cache, TTL, Cache Invalidation và tối ưu hiệu năng Backend
1. Caching là gì? Caching là kỹ thuật lưu tạm dữ liệu đã được tính toán hoặc truy xuất trước đó để có thể sử dụng lại nhanh hơn trong những lần truy cập tiếp theo. Giả sử một API lấy thông tin sản phẩm từ PostgreSQL. Mỗi request đều truy vấn database, chuyển đổi […]
Database Migration
1. Database Migration là gì? Database Migration là quá trình quản lý và áp dụng các thay đổi đối với cấu trúc hoặc dữ liệu trong database theo từng phiên bản có thể theo dõi và kiểm soát. Trong quá trình phát triển phần mềm, database hiếm khi giữ nguyên cấu trúc từ đầu đến […]
Saga Pattern
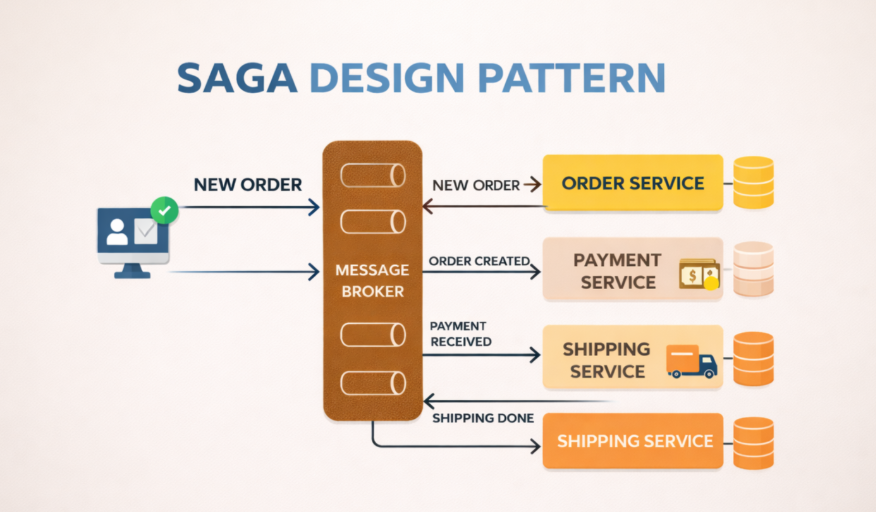
Saga Pattern là gì? Quản lý Transaction trong kiến trúc Microservices 1. Saga Pattern là gì? Saga Pattern là một mẫu thiết kế được sử dụng để quản lý các nghiệp vụ phân tán gồm nhiều bước xử lý, trong đó mỗi bước có thể thực hiện một local transaction tại một service hoặc Database […]
 Khoá học lập trình game con rắn cho trẻ em