Don’t index every column
If indexes are so useful, why don’t we add them to every column?
There are a few good reasons, but a big one is that indexes add overhead to writes. Not only do indexes need to be kept up to date when we write to the table, but they can also prevent optimizations like HOT (Heap-Only Tuple) updates.
As such, the more write-heavy a table is, the more carefully you should think about the benefit of adding an index.
If you’ve inherited a database with too many indexes, you can start to understand how much each one is used with the view pg_stat_user_indexes. Remember to check any read replicas too!
2. Index columns that you filter on
The best candidates for indexes are columns that you filter on regularly. Primary keys are indexed by Postgres automatically, but foreign keys, and other columns, are not.
Let’s consider a simple users table with only two columns:
CREATE TABLE users (
id bigint GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
email text NOT NULL
);
INSERT INTO users (email)
SELECT n || ‘@gmail.com’ FROM generate_series(1, 100000) AS n;
ANALYZE users;
If we want to look up a user by their email address, here is the query plan:
EXPLAIN (ANALYZE, BUFFERS)
SELECT id, email FROM users WHERE email = ‘[email protected]’;
————————————————————
Seq Scan on users (cost=0.00..1887.00 rows=1 width=23) (actual time=21.498..34.505 rows=1 loops=1)
Filter: (email = ‘[email protected]’::text)
Rows Removed by Filter: 99999
Buffers: shared hit=637
Planning Time: 0.113 ms
Execution Time: 34.539 ms
Now let’s add an index on the email column and get a new query plan:
CREATE INDEX users_email ON users(email);
EXPLAIN (ANALYZE, BUFFERS)
SELECT id, email FROM users WHERE email = ‘[email protected]’;
————————————————————
Index Scan using users_email on users (cost=0.42..3.44 rows=1 width=23) (actual time=0.076..0.079 rows=1 loops=1)|
Index Cond: (email = ‘[email protected]’::text)
Buffers: shared hit=4
Planning Time: 0.219 ms
Execution Time: 0.116 ms
We can see from the query plans that using the index is 150x more efficient (4 blocks of data, instead of 637) and 100x faster (0.335ms total instead of 34.652ms). That’s quite a difference, and this is only on 100k rows of data.
Naturally, the lower the proportion of rows filtered out, the less difference an index will make. Once the ratio gets too high, it might not even be faster than a sequential scan – as we saw in our post why isn’t Postgres using my index.
3. Only index data that you need to look up
If you have a proportion of a table that you rarely look up, and almost always filter out, there is little benefit to having it indexed. A common example given is a table containing soft-deleted data, where queries will normally contain WHERE deleted_at IS NULL
For these cases, Postgres has partial indexes. These are smaller, faster, and don’t need to be updated as often as full indexes. You do need to be careful, though, as they can only be used for queries that Postgres can guarantee matches the WHERE condition.
4. Consider other index types
You can get quite far with the trusty b-tree index – which is the default for good reasons!
But there are some cases where learning what else is available can pay off big-time. There is a good list of the in-built index types in the Postgres documentation, so I’m not going to re-hash (sorry) the details here.
The short version is that some index types can be faster, or much smaller, for specific use cases, while others can enable things that b-trees don’t support, like full-text search, or spatial queries.
5. Use indexes to pre-sort data
Sorting a large dataset is an expensive operation, in both time and memory.
Sorting the same data over and over can be avoided by adding an index with the order needed. As of PostgreSQL 13 (Sep 2020), it can even do an Incremental Sort, making use of an index that only satisfies the first part(s) of the sort order.
For an added performance boost, it is great to load data in a sorted fashion. This will reduce the number of page reads needed for queries using the sort order, making your queries more efficient, and again, faster.
6. Use multi-column indexes, but sparingly
Postgres lets you add more than one column to an index. You can order by a second (and third, etc) column, or include the additional column(s) in the payload to enable index-only scans.
However, as we noted when we wrote about multi-column indexes, there are downsides to consider. Postgres does have other options, so our advice is to use multi-column indexes, but to do so sparingly.
7. Look after your indexes
Indexes can require a bit of looking after (or maintenance) to stay performant over time.
Vacuum (and autovacuum) will clear out deleted (and updated) entries, but it won’t re-combine pages that are mostly empty. As such, over time your index can grow in size, and reduce in efficiency: an effect often referred to as bloat.
You can monitor for signs of bloat, and you can also see clues in query plans (when you use BUFFERS). It is one of the types of issue pointed out in our product, pgMustard.
To completely remove bloat from an index, you can use REINDEX. As of Postgres 12, we have the very useful REINDEX CONCURRENTLY, but you do need to be careful if that ever fails, as it can leave behind invalid indexes. pg_repack and pg_squeeze are other options that involve minimal locking.
8. Pick your battles
It is easy to spend hours tuning a single query, so it is pretty important to prioritize well.
There are lots of monitoring tools and extensions available to help you find your biggest bottlenecks. A popular tool among pgMustard customers is the trusty pg_stat_statemements.
In summary Here’s a quick recap of the best practices we covered for indexing in postgresql
Don’t index every column
Index columns that you filter on
Only index data that you need to look up
Consider other index types
Use indexes to pre-sort data
Use multi-column indexes, but sparingly
Look after your indexes
Pick your battles
REF
https://www.pgmustard.com/blog/indexing-best-practices-postgresql

Bài viết khác
Redis & Caching là gì?
Redis & Caching là gì? Hướng dẫn sử dụng Redis trong Go 1. Caching là gì? Vì sao cần cache khi đã có database? Caching (bộ nhớ đệm) là kỹ thuật lưu tạm dữ liệu thường được truy cập để có thể lấy lại nhanh chóng khi cần, thay vì phải thực hiện lại toàn […]
Database Migration là gì?
1. Database Migration là gì? Database Migration là quá trình quản lý và áp dụng những thay đổi đối với cấu trúc hoặc dữ liệu trong cơ sở dữ liệu theo từng phiên bản của ứng dụng. Trong quá trình phát triển phần mềm, yêu cầu nghiệp vụ thường xuyên thay đổi. Một bảng có […]
Bun ORM là gì?
Bun ORM là gì? Hướng dẫn sử dụng Bun ORM với Go và PostgreSQL 1. Bun ORM là gì? Bun là một thư viện ORM dành cho ngôn ngữ Go, được thiết kế theo hướng SQL-first. Thay vì cố gắng che giấu hoàn toàn SQL phía sau các phương thức trừu tượng, Bun cho phép […]
Redis & Caching – Hướng dẫn toàn diện về Cache, TTL, Cache Invalidation và tối ưu hiệu năng Backend
1. Caching là gì? Caching là kỹ thuật lưu tạm dữ liệu đã được tính toán hoặc truy xuất trước đó để có thể sử dụng lại nhanh hơn trong những lần truy cập tiếp theo. Giả sử một API lấy thông tin sản phẩm từ PostgreSQL. Mỗi request đều truy vấn database, chuyển đổi […]
Database Migration
1. Database Migration là gì? Database Migration là quá trình quản lý và áp dụng các thay đổi đối với cấu trúc hoặc dữ liệu trong database theo từng phiên bản có thể theo dõi và kiểm soát. Trong quá trình phát triển phần mềm, database hiếm khi giữ nguyên cấu trúc từ đầu đến […]
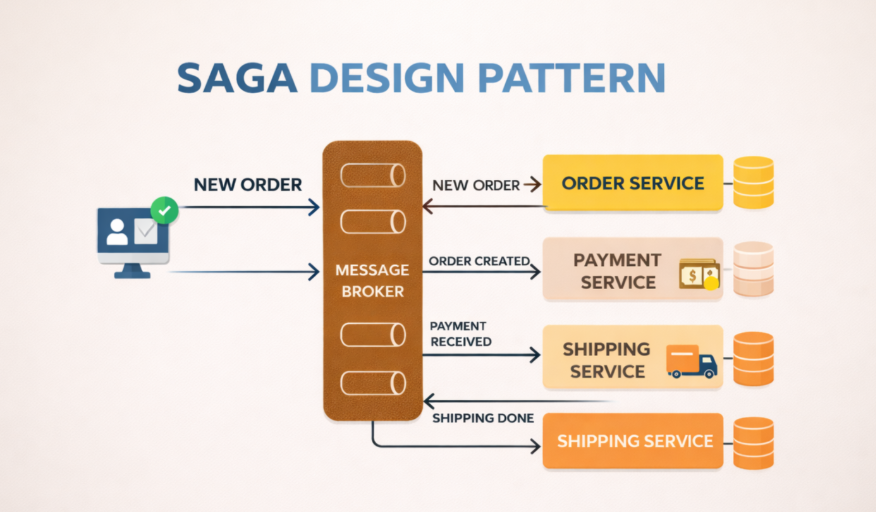
Saga Pattern
Saga Pattern là gì? Quản lý Transaction trong kiến trúc Microservices 1. Saga Pattern là gì? Saga Pattern là một mẫu thiết kế được sử dụng để quản lý các nghiệp vụ phân tán gồm nhiều bước xử lý, trong đó mỗi bước có thể thực hiện một local transaction tại một service hoặc Database […]
 Khoá học lập trình game con rắn cho trẻ em